Hiker on a mountain summit

From the Team

The RidgeText Blog

Deep dives on how we build — AI architecture, mapping, and outdoor technology.

Dispersed Camping Layer: Mapping Where Dispersed Camping Is Allowed

Dispersed Camping Layer: Mapping Where Dispersed Camping Is Allowed

How RidgeText answers dispersed camping questions by text, combining land managers, open forest roads, campgrounds and the camping corridors printed on Forest Service motor vehicle use maps, including the scanned ones.

campingmapsllmpublic-lands
Raising Worker Concurrency While Keeping Replies Single-Threaded per User

Raising Worker Concurrency While Keeping Replies Single-Threaded per User

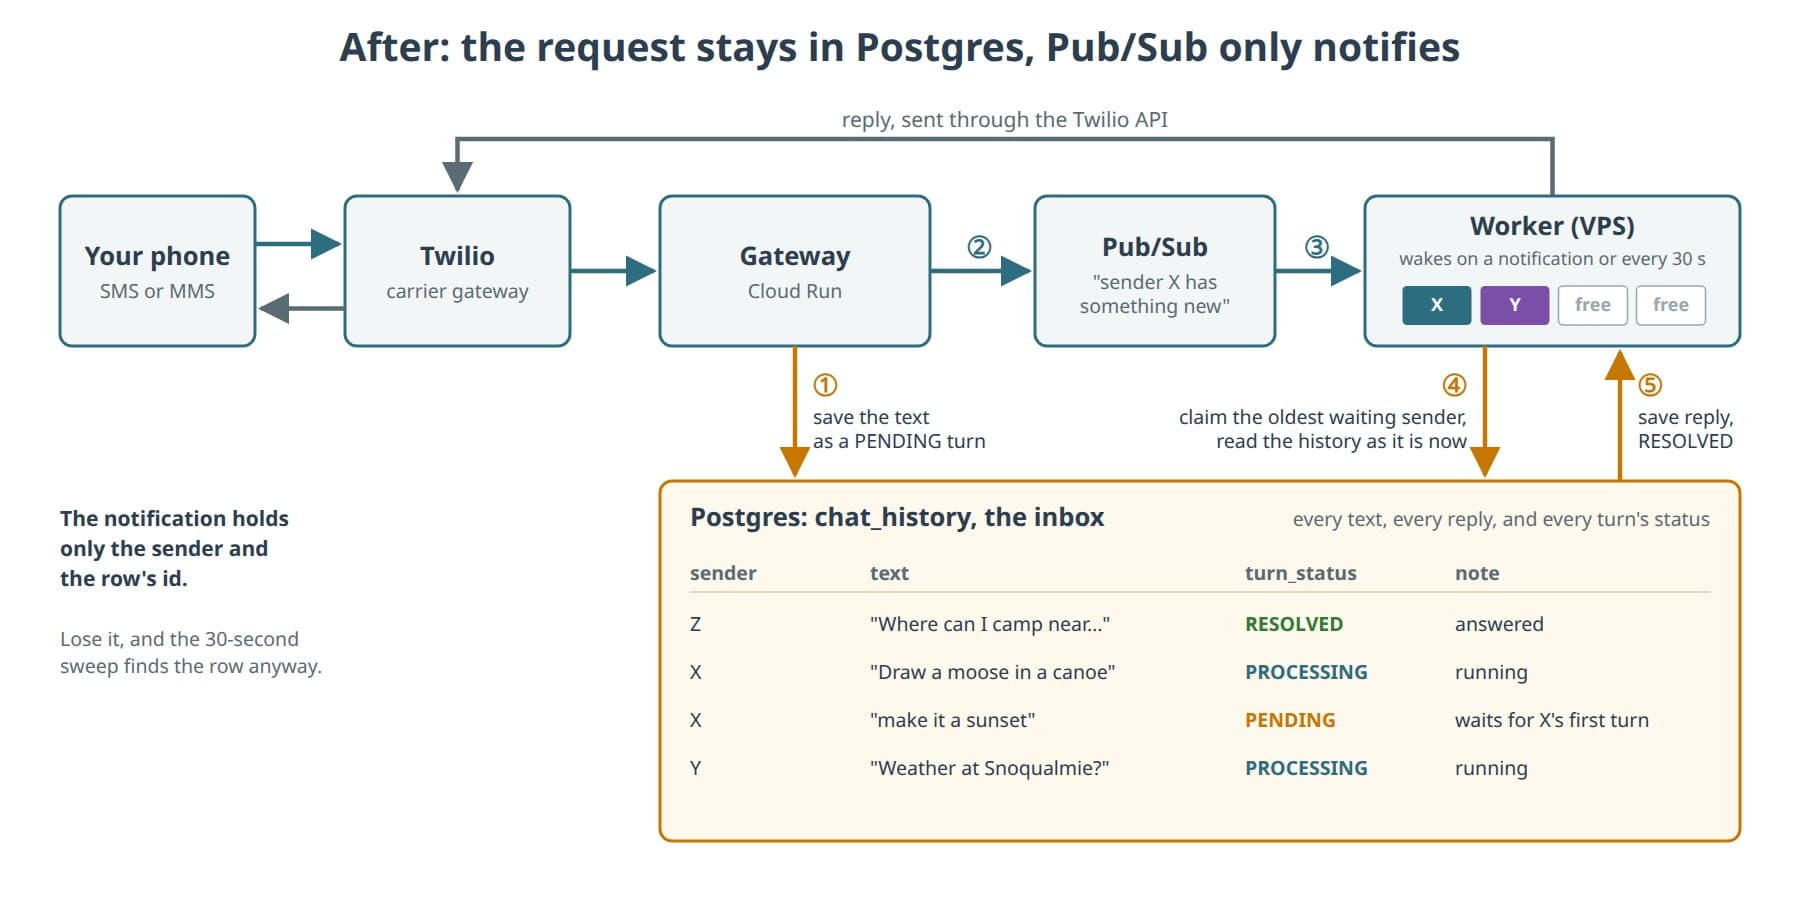
How we took RidgeText's SMS worker from one Pub/Sub message at a time to four concurrent turns while serializing each sender's messages, by claiming turns from a Postgres table with an advisory-locked query and reducing Pub/Sub to a wake-up notification.

architecturepubsubpostgresconcurrencysystems-engineering
How Sure Are You? Measuring Confidence When RidgeText Identifies a Photo

How Sure Are You? Measuring Confidence When RidgeText Identifies a Photo

Why a language model's own confidence rating can't be trusted, and how RidgeText now asks three independent checks to identify a photo and reports how well they agree.

llmphotoswildlifeengineering
SMS Pumping: You May Be Paying an Attacker Through a Revenue Share

SMS Pumping: You May Be Paying an Attacker Through a Revenue Share

How a login code becomes someone else's paycheck, who collects the money along the way, and what any company that sends verification texts can do about it.

securitysmstransparency
Don't forget to be funny

Don't forget to be funny

We replaced our linear memory with three kinds of memory — semantic recall, permanent facts, and transient notes — and learned a lot about how to be funny.

architecturememorypgvectorgeminisystems-engineering
How we reduced LLM cognitive load with the Sub-Agent-as-a-Tool pattern

How we reduced LLM cognitive load with the Sub-Agent-as-a-Tool pattern

Piling 15+ complex tools into a single LLM was causing context confusion. Here's why we bypassed top-level routing, embraced the Sub-Agent-as-a-Tool pattern, and built a generic multi-agent backend that scales.

architectureagentic-designgeminisystems-engineering
How we cut our cloud bill 85% by splitting one service across two machines

How we cut our cloud bill 85% by splitting one service across two machines

A single always-on Cloud Run instance was costing us $160/month for compute headroom we only needed during LLM tool calls. Here's how we reshaped the system around Pub/Sub and a small dedicated worker — and what the latency numbers actually looked like.

architecturecloud-runpubsubcost-optimization
How One User Can Ruin It for Everyone Else - The Image Loophole

How One User Can Ruin It for Everyone Else - The Image Loophole

One User. Seven Days. 1,074 AI Images.

platformtransparencycredits
Mapping with In-Memory Layers to Reduce LLM Overload

Mapping with In-Memory Layers to Reduce LLM Overload

How we built a Mapbox-compatible map compositor where the LLM orchestrates layers without ever touching GeoJSON — keeping context windows small and rendering deterministic.

mapboxllmarchitecturemapping

Ready to explore?

Start with a free plan and text RidgeText from wherever your adventure takes you.